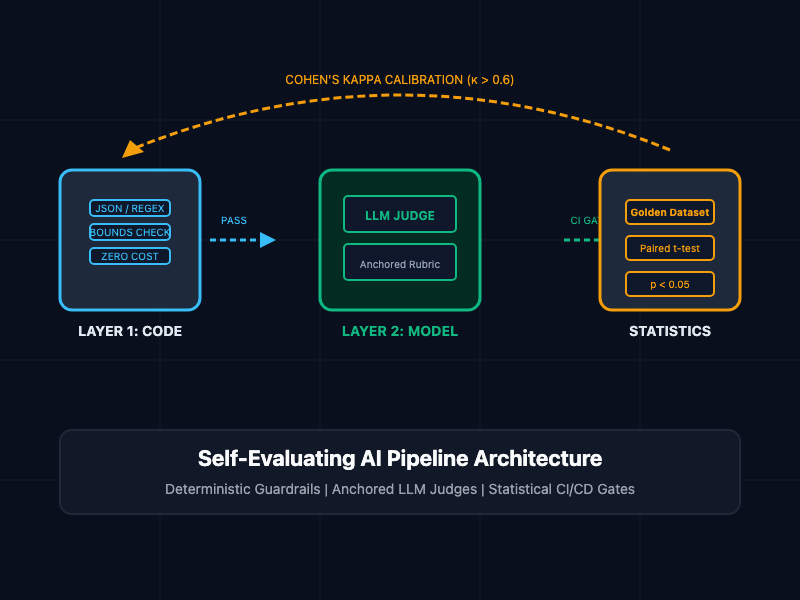
Traditional assertions fail when evaluating non-deterministic LLMs. Building a self-evaluating AI system requires a three-layer testing pipeline: instant deterministic validation, structured LLM-as-a-judge scoring with rubric anchors, and periodic human alignment. Learn how to construct golden datasets, run paired t-tests for statistical significance, and gate CI/CD merges. #LLMOps #AIEvaluation #MachineLearning #Python #DevOps #SoftwareTesting #GenerativeAI #PromptEngineering #SRE #AIQuality

Our Products
oDesk Software Co., LTD
No products available right now. Check back soon or explore our services.